Enterprise AI Beyond the Pilot: What Separates Programs That Scale
ⓘ TL;DR
- Scaling enterprise AI requires building a mature operating model with clear data ownership and human review rather than relying solely on platform capabilities.
- Evaluate returns before scaling by establishing pre-deployment baselines and tracking cost savings, revenue lift, and productivity across separate ledgers.
- Ensure data privacy compliance by establishing data lineage, audit trails, retention windows, and explicit consent policies prior to model deployment.
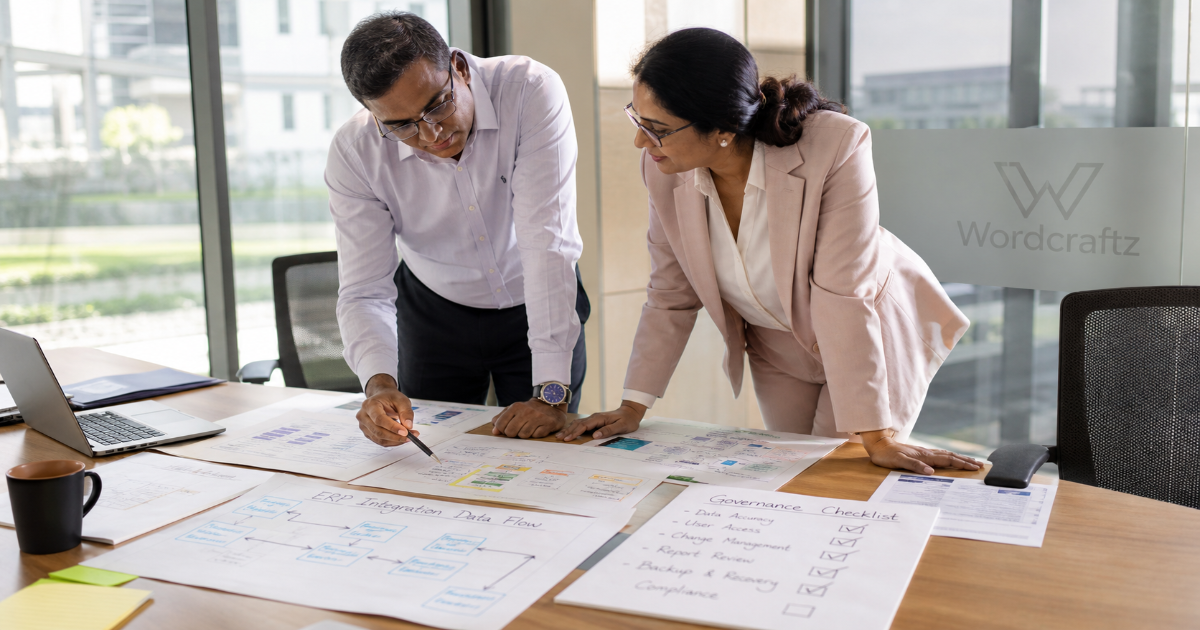
- Prevent integration failures by mapping all legacy ERP and CRM data flows and running parallel operations prior to cutover.
- Move beyond the pilot phase by assigning named executive owners, establishing operational metrics, and training staff on workflow changes.
A stalled enterprise AI pilot costs more than the platform license. It burns the credibility of the team that championed it, and that credibility is the hardest budget line to rebuild. The technology usually works. The operating model around it does not. Enterprise AI programs that scale treat measurement, governance, integration, and ownership as the product, not the model weights.
This article walks through how to measure returns before scaling, what compliance obligations attach to your deployment, how to connect AI to legacy ERP and CRM systems, and why pilots die before production. Here you’ll find the conditions that separate a demo from a capability.
Kubernetes and Docker adoption followed the same curve. The tools worked early. The operating practices took years to mature. Enterprise AI sits at that same inflection point. The teams pulling ahead build operational discipline before scaling the deployment.
Enterprise AI Is an Operating Model, Not a Tool
Enterprise AI is the strategic deployment of artificial intelligence across an organization’s core operations, not the installation of a single product. The strategic deployment of AI technologies covers machine learning, natural language processing, and computer vision running inside large-scale business environments. That definition matters because it puts the emphasis on deployment, not purchase.
Buying the platform takes a quarter. Making it work takes a different kind of effort. Enterprise AI goes beyond simple automation, solving problems that demand human-like intelligence: reading customer behavior, rerouting logistics, flagging fraud before settlement. A tool answers a question. A capability changes how the organization decides.
The misunderstanding starts with scope. A department buys a summarization tool, runs it against a clean dataset, and calls the result transformation. Then the tool meets production data with gaps, duplicates, and no owner. The operating model around the platform decides outcomes, not the platform itself. Data ownership, review processes, and named accountability are the parts nobody puts in the purchase order.
Contrast that with an organization-wide capability. Someone owns the data. Someone reviews the model’s output before it reaches a customer. Someone’s name sits next to the decision when it goes wrong. Those three roles cost more than the license and matter more than the model’s benchmark score.
Get the operating model right and the platform choice becomes almost interchangeable. Get it wrong and the best model on the market stalls in a pilot. Audit who owns the data, who reviews the output, and who answers when it fails before you sign the next contract.
The counter-argument arrives fast: the platform is the hard part, so buy the best one and the rest follows. That logic worked for spreadsheets. It fails here because models degrade, drift, and surprise you after launch.
Governance is not a committee you form later. It is the review step that catches a hallucinated refund policy before a customer reads it. Build that step before the pilot ends, not after the first incident.
How to Measure Enterprise AI Returns Before You Scale
Enterprise AI business cases collapse when the numbers arrive after deployment. Build the measurement model first, and the go or no-go decision becomes arithmetic instead of advocacy.
Step 1. Capture the baseline before anything ships. Record current cycle times, error rates, headcount cost, and conversion figures for the exact process the system will touch. Skip this and every later claim becomes unfalsifiable.
Step 2. Split the return into three separate ledgers. Cost savings, revenue lift, and productivity gains behave differently and deserve separate tracking. Mixing them into one blended figure hides which category is carrying the program.
Step 3. Price each category in dollars, not percentages. Convert hours saved into loaded salary cost and conversion gains into average deal value.
Step 4. Treat productivity as the weakest claim on the sheet. Enterprise AI is applied to boost workforce efficiency and productivity, and that category is the hardest to price and the easiest to inflate. Time saved rarely converts to headcount removed, so count it only where a role was genuinely eliminated or reassigned.
Step 5. Subtract implementation and run costs before you present anything. Include integration labor, data cleanup, licensing, and ongoing maintenance nobody budgets for. A program that clears its baseline by a thin margin will not survive its first renewal.
Step 6. Rebuild the model every quarter with real numbers. Replace projections with actuals as they land, and flag any category drifting more than a fifth from forecast. measuring return on investment this way turns the business case into a living document rather than a one-time pitch.
Completing the sequence gives you a defensible number and a clear trigger for scaling or stopping. That number is what buys the next phase of the budget.
The counter-argument arrives fast: if the model is this strict, nothing gets funded. Fair concern, and it misses the point. The model does not block spending, it blocks spending on the wrong category, which is a different decision entirely.
Run the six steps on a program with a weak productivity case and a strong cost case. The cost ledger carries the approval, and the productivity claim gets parked until a role is genuinely reassigned. That is the model working, not failing.
Data Privacy and Compliance Rules for Enterprise AI
Enterprise AI compliance splits into four problems that look related and are not. Broad privacy law governs personal data. Sector rules override it. Auditing proves what the model did. Consent language decides whether any of it holds up. Treat them as one checklist and you will pass a legal review while failing an audit.
Where Broad Privacy Law Reaches AI Systems
Data protection rules were written for databases, not inference pipelines. A model that ingests customer records, retrains on them, and outputs a prediction is processing personal data at every stage. The GDPR’s purpose limitation principle means data collected for billing cannot quietly become training material.
Deletion requests expose the gap. Removing a record from a table is simple. Removing its influence from a trained model is not, and companies that never planned for this end up retraining from scratch or documenting why they cannot.
How Sector Rules Override General Privacy Law
Healthcare adds HIPAA. Financial services adds its own supervisory expectations. Real estate adds fair housing scrutiny to any model that touches tenant screening or lending. Each layer narrows what a general privacy program already permits.
A fraud detection model that would pass a standard privacy review can still fail fair lending examination if its features correlate with protected classes. Sector rules test outcomes, not just data handling.
What Model Auditing Actually Requires
Auditing means reconstructing a decision after the fact. That demands versioned training data, logged model versions, and a record of which inputs produced which outputs. Without data lineage, an auditor cannot tell whether a denial came from the model or the rule layered on top of it.
Documentation has to be written during development. Reconstructing it later produces a narrative, not evidence.
Writing Consent and Data Handling Policies Before Deployment
Consent language written after launch describes what already happened. Written before, it constrains what the system is allowed to do. The difference shows up the first time a regulator asks what customers agreed to.
The compliance burden sits with the organization deploying the system, not the vendor. Vendor terms transfer liability on paper and rarely in practice. Regulated brands in healthcare, real estate, and corporate sectors need governance and consent content that states data practices in plain language, and Wordcraftz helps those teams write documentation that holds up to scrutiny. Clear language also builds trust in AI search and automated decisions, where vague policy language reads as concealment. Retention windows, human review of automated decisions, and data lineage belong in that document.
Connecting Enterprise AI to Legacy Systems
Enterprise AI integration succeeds or fails on the quality of the mapping work done before a single connection is built. Teams that skip straight to configuration spend months untangling data flows nobody documented, and the cost lands on the operations staff who never asked for the project.
Step 1. Map every system, data flow, and integration point before writing any code. Trace where customer records originate, where they get duplicated, and which team treats each system as authoritative. Skip this and you will discover conflicting customer IDs in production, after the AI layer has already made decisions on corrupted records.
Step 2. Decide between direct API connections and middleware based on volume and change frequency. Direct connections work when two systems talk infrequently and the schema rarely shifts. Middleware earns its cost when multiple systems need the same data and enterprise AI platforms must reconcile it consistently.
Step 3. Run parallel operation before any cutover. Keep the legacy process running alongside the new system and compare outputs daily until they match. Cutting over early means you lose the ability to isolate whether a wrong answer came from the model or the data feed.
Step 4. Assign an integration owner from the team that actually operates the legacy system. The people who understand the ERP are rarely the people building the AI layer. Without that bridge, the AI team ships something technically correct and operationally unusable.
Step 5. Brief the teams who use the systems before the change goes live, not after. Adoption depends on workflow and funnel alignment, and staff who learn about a new process through a ticket queue will route around it. Wordcraftz helps technology teams write the internal communication that makes a system change legible rather than threatening.
Finishing this sequence gives you an AI layer that reads from systems people already trust. The integration holds because the people who run the legacy stack helped build the bridge to it.
Why Enterprise AI Pilots Never Reach Production
Enterprise AI pilots die in the gap between the demo and the operating floor. The model performs, the slides land, and the program still stalls. What fails is the environment the model was dropped into, not the model itself.
This pattern repeats because the pilot is designed to succeed in isolation. Sample data is clean by default, the demo has a hero, and accuracy is easy to measure. The reasoning breaks the moment the system meets production data and nobody owns the outcome.
Before: A retail operations team runs a demand-forecasting pilot on a curated dataset pulled from a single warehouse. The vendor’s model hits strong accuracy in testing, and the team presents the results to leadership with confidence. Nobody assigns a permanent owner once the demo ends, and success is defined as model precision rather than inventory cost. Six months later the model sits in a sandbox, the budget lapses, and the team that championed it loses credibility for the next ask.
After: The same team starts by auditing production data quality across every warehouse before writing a line of code. They name an accountable owner with budget authority and a mandate that outlasts the pilot phase. Success is defined operationally: reduced stockouts, lower carrying cost, faster replenishment cycles. The model becomes a component of a process someone is responsible for, not a standalone experiment.
The contrast exposes the real constraint. Pilots are judged on what the technology can do, while production programs are judged on what the business can sustain. That shift requires ownership, data discipline, and operational definitions of success long before the first deployment occurs. The same logic holds for the content and messaging that surrounds a rollout, where consistency across campaigns determines whether employees and customers trust the change. A pilot without an owner and an operational target is a demo with a longer timeline. Scale follows the conditions you build around the model, never the model alone.
Build or Buy: The Trade-Offs of an AI Factory
Three paths exist for enterprise AI infrastructure, and the choice between them is a control decision disguised as a budget decision. What separates them is who owns the data path, who carries the fixed cost, and what skills you must hire.
A hosted platform wins on speed. You sign, you configure, you deploy, and the vendor absorbs the hardware risk. That works for teams testing a use case or running workloads that tolerate public-cloud residency. Where it falls short is control: you inherit the vendor’s roadmap, pricing changes, and region constraints, and moving off later costs more than starting there did.
Building on a validated on-premise design flips that equation. A full-stack validated design now exists for enterprises that want to build and deploy their own on-premise AI factory, which removes the guesswork from hardware selection and software stacking. Control and data residency are total, and the cost structure shifts from recurring subscription to capital investment that depreciates. The catch is skills. You need infrastructure engineers, not just data scientists, and that hiring takes months.
A hybrid approach splits workloads by sensitivity. Regulated data stays on-premise; experimentation and low-risk inference run hosted. This is the most common landing point for large organizations, and also the hardest to operate. Two environments mean two governance regimes, two cost models, and a constant question about where any given model should live.
Control is the variable that decides this, not cost. If your data cannot leave your perimeter, hosted is not a real option regardless of price. If your workloads are exploratory and your team is small, on-premise capital will sit idle.
Choose hosted when speed matters more than residency and your team lacks infrastructure depth. Choose on-premise when data residency is non-negotiable and you can fund the hiring. Choose hybrid only when you have the operational maturity to run both, and treat matching message to purpose across internal teams as part of the rollout, not an afterthought.
The Part Most Enterprise AI Guides Get Wrong
Enterprise AI programs stall on the human layer, not the model layer. Guides treat the rollout as a procurement exercise: pick a vendor, sign the contract, watch adoption happen. Adoption does not happen on its own.
- The communication layer. Employees resist systems they cannot explain to themselves. If nobody tells a claims team why an AI tool changes their queue, they route around it within weeks.
- The ownership gap. Pilots get a champion. Production gets an orphan. Someone with budget authority has to own the system after launch, or it quietly loses its funding line.
- Measurement discipline. The first bad quarter kills more programs than any technical failure. Teams that pre-commit to what success looks like survive it. Teams that improvise abandon the system.
- The training burden. Nobody budgets for retraining a workforce on new workflows. The cost shows up later as shadow processes and quiet non-use.
- strategic content translation. Governance documents, consent language, and internal rollout messaging all need rewriting for a non-technical audience. Skip that step and the system ships with instructions nobody reads.
Read those five items together and a pattern appears. Each one is a communication or accountability problem wearing a technical costume. The platform was never the hard part. What changes when teams treat these as first-class requirements is simple: the rollout stops being a launch and starts being an operating capability.
Wordcraftz builds the internal and customer-facing messaging that makes new systems understandable rather than threatening, which is often the difference between a system people use and one they tolerate. Audit these five before your next phase approval.
The counter-argument is fair: governance slows things down, and speed is the whole point of a pilot. That logic holds right up until the first audit, when nobody can explain how the model reached a decision. Speed without a paper trail is borrowed time. One regulatory review can freeze a program that took two quarters to build.
Turn Your Enterprise AI Pilot Into an Operating Capability
Enterprise AI programs that scale share four conditions: measurement, governance, integration, and ownership. Model quality sits far down that list. A mediocre model inside a disciplined operating model outperforms a strong model inside a chaotic one.
Audit those four conditions before approving the next phase. Programs that skip this step discover the gap after cutover, when rollback costs exceed the original build. The teams that run the audit first move into production with evidence, not optimism. Start with ownership. Confirm a named executive holds budget authority for the program. Then verify your baseline, your governance documentation, and your integration path. Fix what fails.
Wordcraftz turns scattered ideas into messaging that wins trust and drives sales. Book a free strategy call today to see what clear, confident copy can do for you.
Enterprise AI Questions Teams Ask Before Scaling
How do you calculate ROI on an enterprise AI investment?
ROI comes from comparing a pre-deployment baseline against three separately priced ledgers: cost savings, revenue lift, and productivity gains. Productivity is the ledger teams inflate most, because hours saved rarely convert into headcount removed, so price it last and conservatively.
What compliance obligations apply to AI systems that handle personal data?
Obligations sit with the organization deploying the system, not the vendor, and cover data lineage, retention limits, and human review of automated decisions. Consent language has to be written before deployment, because retrofitting disclosure onto a live model means retraining or removing data you cannot legally keep.
How do you integrate AI with legacy ERP and CRM systems?
Map every system and data flow first, then choose between direct API connections and middleware before writing any model code. Run the AI layer in parallel with the legacy process until outputs match, because cutover failures trace back to undocumented data flows rather than to the model itself.
Why do enterprise AI pilots fail to reach production?
Pilots stall because they run on clean sample data, lose their named owner after the demo, and get judged on model accuracy instead of business outcome. Programs that scale define success in operational terms before the first line of code and keep an accountable owner with budget authority attached through launch.